San Diego / California
Dr. ZhaoTang
Software Engineer · Data & AI Systems
I build reliable data platforms, measurable AI products, and production systems that hold up under real load.
Build / Measure / Operate
- 100M+TurboTax and QuickBooks users supported by Intuit data products
- 40%Lower MTTR through distributed tracing and root-cause analysis
- 0.840Hybrid Hit@5 on GraphAtlas's 50-question benchmark
- 6Peer-reviewed publications, plus conference posters and presentations
01 / Selected work
Systems built for evidence, not just demos.
Streaming infrastructure, retrieval engineering, governed analytics, and scientific computing—with measured outcomes and explicit boundaries.
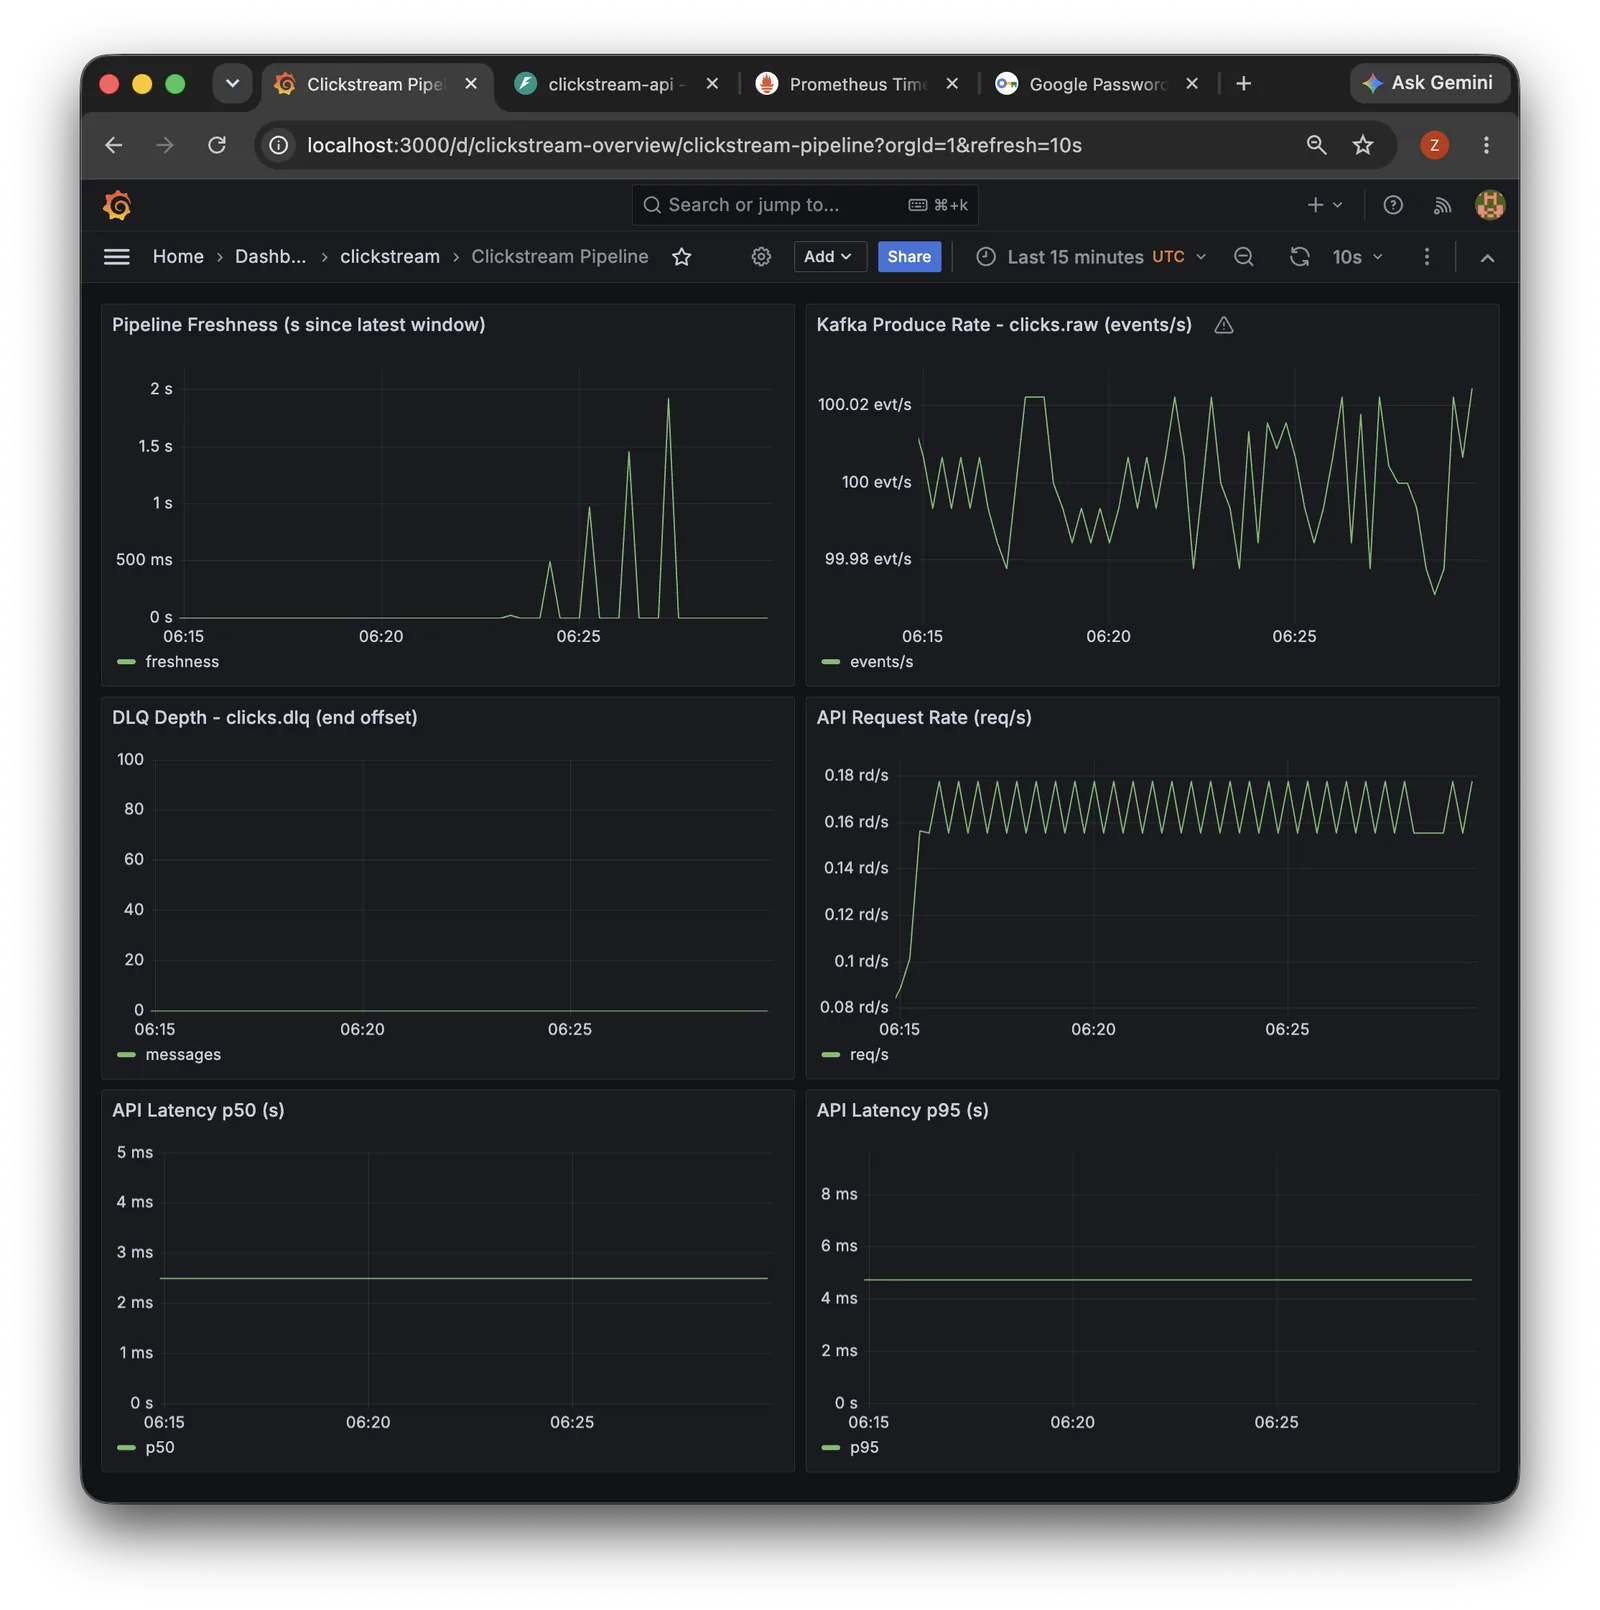
Streaming data platform
Clickstream
An end-to-end streaming platform that turns high-volume events into monitored, queryable data products.
- ~100 events/s
- p95 181 ms
- 111
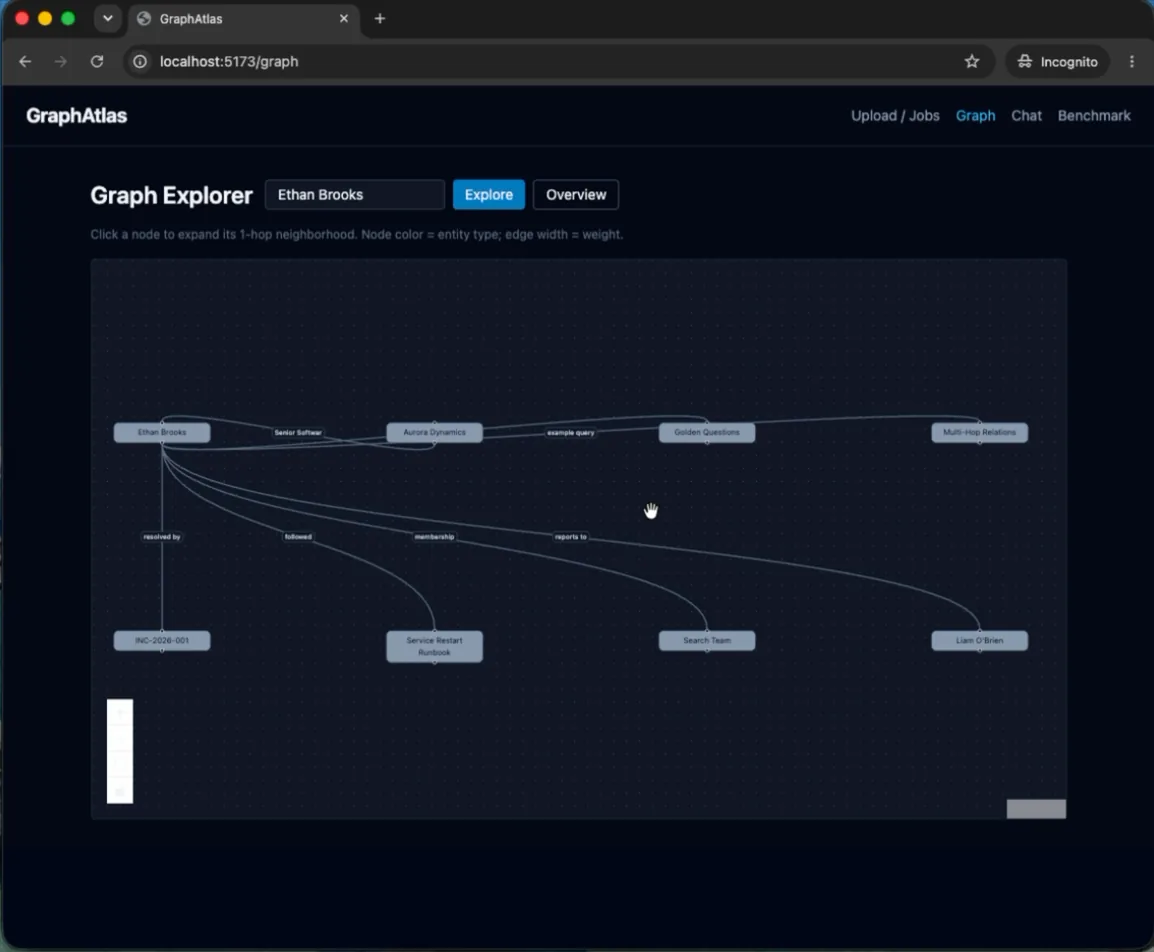
GraphRAG · Retrieval engineering
GraphAtlas
A multi-engine knowledge platform with traceable citations and an evaluation harness that makes retrieval quality measurable.
- 0.840 Hit@5
- 537 ms p95
- 4.38 / 5
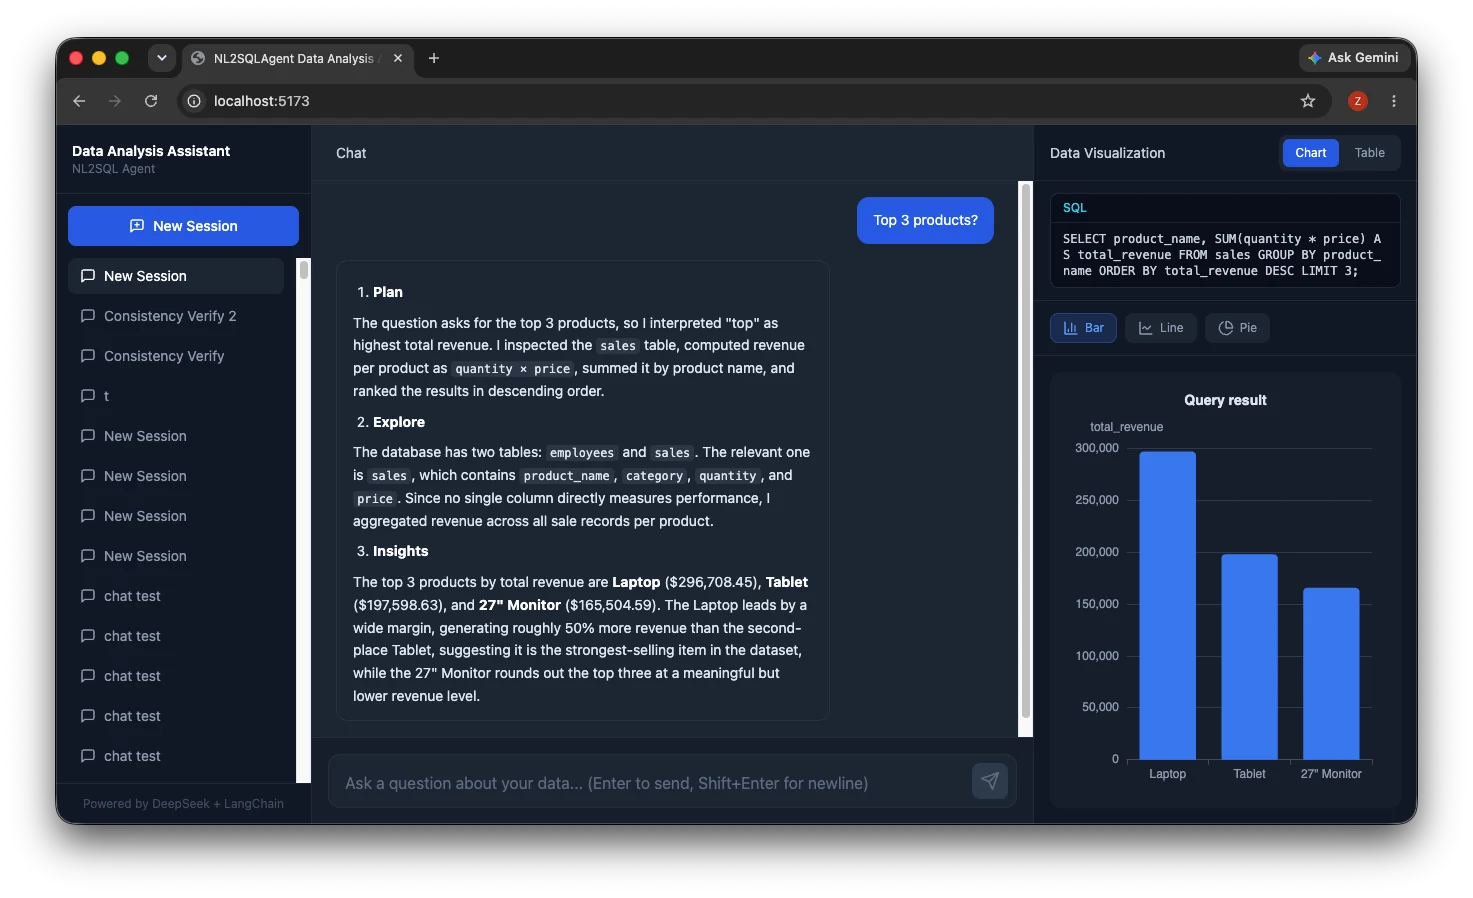
Governed AI analytics
NL2SQLAgent
A natural-language interface to a million-row warehouse, designed so generated SQL stays inspectable and read-only.
- 1.03M rows
- <250 ms
- 7–15 s
Research data infrastructure
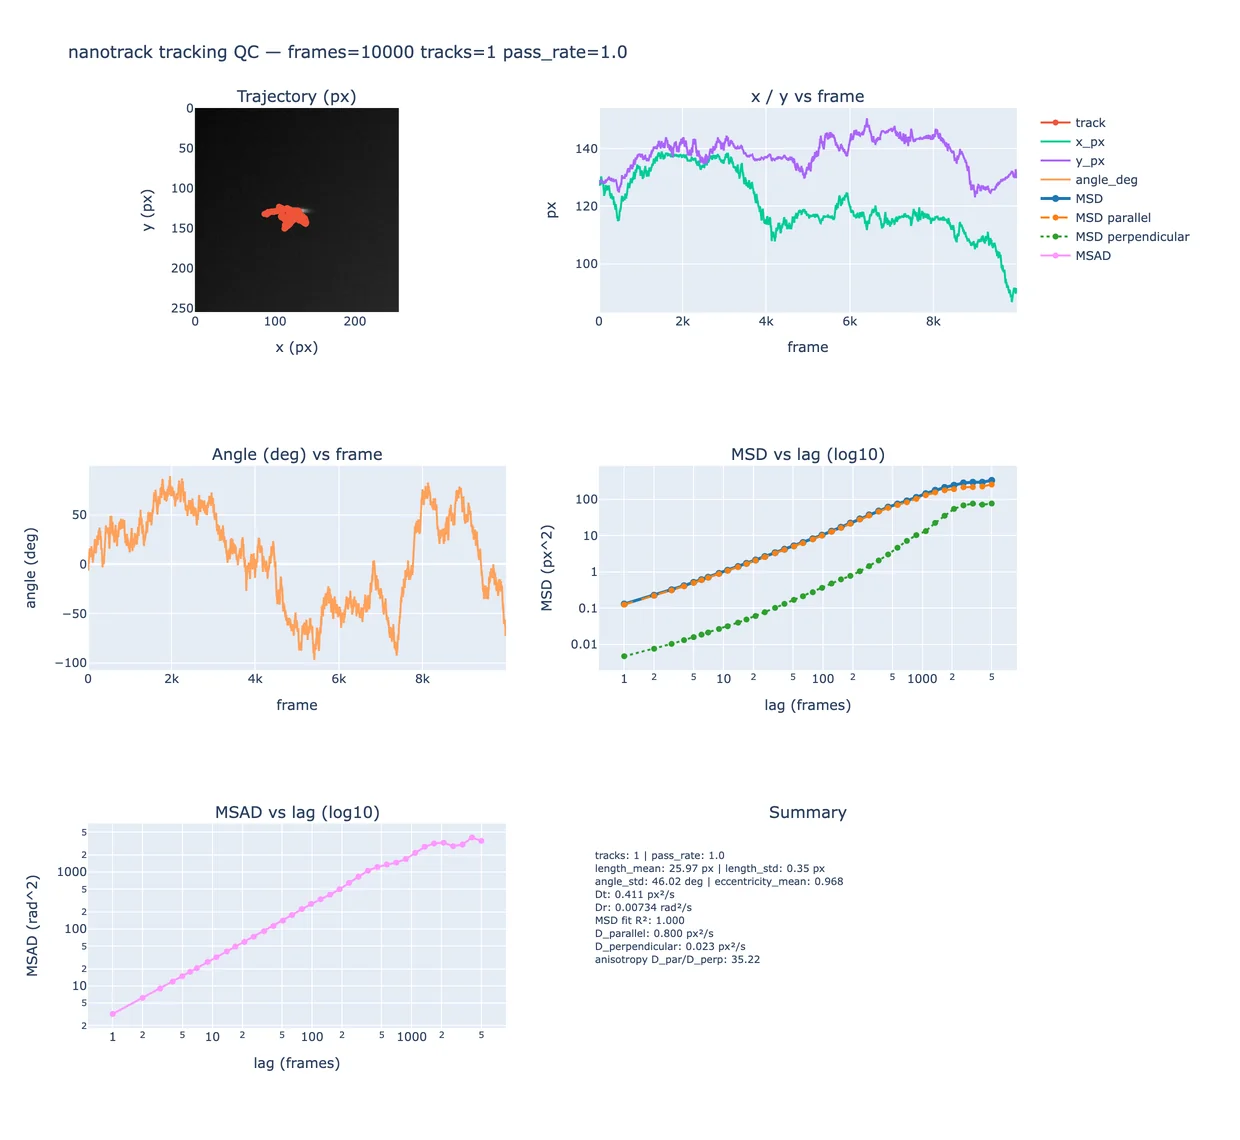
nanotrack
A scientific video-tracking pipeline rebuilt from MATLAB into a reproducible Python system with orchestration, observability, and CI.
- 15 h → 30 min
- 6
- 10k
02 / Experience
Where data correctness meets system reliability.
I have worked across real-time data platforms, customer-facing measurement, production incident response, and research software. The common thread is making complex systems observable, reproducible, and useful to the people who depend on them.
Owned production data quality and measurement while serving as primary on-call engineer.
- Cut MTTR by 40% using distributed tracing and root-cause analysis, with durable corrective actions and runbooks.
- Led a cross-organization remediation of millions of missing records and aligned three organizations on one metric definition and validation standard.
- Raised experiment device coverage by 10+ percentage points, moving from the mid-60s to the high-70s.
- Upgraded batch pipelines to incremental processing, reducing peak processing time from 7 hours to 15 minutes and peak infrastructure cost by 95%.
- Built validation and monitoring that surfaced incorrect data before it reached reporting.
Built real-time data platforms and foundational datasets for products used by more than 100 million people.
- Built real-time pipelines and datasets powering daily decisions for 100M+ TurboTax and QuickBooks users.
- Mapped dependencies across 100+ pipelines and approximately 1,000 tables, cutting manual cross-team approval coordination by about 50%.
- Fixed a multi-year stateful defect, restoring cumulative tracking since 2020 for 10M+ unique visitors and 1M+ daily sessions.
- Used internal AI tooling to deliver 10+ pipelines with code review and end-to-end validation.
Engineered reproducible data infrastructure for multi-terabyte scientific datasets.
- Built Python workflows with automated validation and greater than 99% data consistency for scientific users.
- Parallelized multi-terabyte video and unstructured-data processing on HPC clusters.
- Re-engineered a MATLAB tracking methodology into the open-source nanotrack Python pipeline.
Built computational-imaging and machine-learning pipelines for single-molecule and nanoparticle analysis.
- Developed automated image-processing and optical-analysis software in Python and MATLAB.
- Reduced per-experiment processing time from 15 hours to 30 minutes through cluster parallelization.
- Published methods and datasets that support 6 peer-reviewed papers, with additional conference posters and presentations.
03 / About
I care about the part after the demo works.
Science taught me to treat measurement as part of the system. Industry taught me that correctness only matters if it survives real traffic, changing schemas, ambiguous definitions, and the person who gets paged at 2 a.m.
I started in computational imaging and completed a PhD at Rice, building software to extract measurable signals from complex scientific data. At Intuit, I moved into real-time data platforms and customer-facing data products: defining data-quality metrics, stabilizing stateful pipelines, tracing production failures, and aligning teams on one definition of truth.
Today I focus on systems where data, AI, and reliability meet: streaming pipelines, retrieval and evaluation, governed natural-language analytics, and the observability that keeps them operable.
Technical toolkit
Built across data, platforms, and AI.
- Data & streaming
- Python · SQL · Spark · Kafka · Airflow · dbt · Databricks · Delta Lake · PostgreSQL · ClickHouse · Redis
- Cloud & reliability
- AWS · Docker · Kubernetes · Helm · Terraform · GitHub Actions · Prometheus · Grafana · Linux
- Backend & APIs
- FastAPI · REST · Server-Sent Events · TypeScript · Hono
- AI & retrieval
- pgvector · RAG / GraphRAG · Reciprocal Rank Fusion · LLM evaluation · LangChain
- Languages
- Python · SQL · Scala · Go · TypeScript / JavaScript · Bash
04 / Research
Measurement, reproducibility, and scientific computing.
My research background spans computational imaging, single-molecule tracking, machine learning, and research data infrastructure. The work produced 6 peer-reviewed publications, along with conference posters and presentations, and taught me to preserve provenance, validate methods, and make complex results reproducible.
- Computational imaging
- Single-molecule tracking
- Machine learning
- Research data infrastructure
05 / Contact
Let’s build systems that can be trusted after launch.
For roles, collaborations, or technical conversations about data platforms, production AI, and reliability, reach me at the links below.
ztangintuit@gmail.com