Controlled AI research agent
Job Fit Research Agent
A controlled DeepAgents workflow that turns local job descriptions into inspectable recommendations with exact source quotes, a fixed rubric, and an audit manifest.
ScopeIndependent offline-first prototype using synthetic profiles and job descriptions. Not production software, not a hiring system, and not used to submit applications.
- synthetic evaluation agreement
- 15 / 15
- evidence coverage
- 100%
- unit tests
- 40
- Python
- DeepAgents
- LangChain
- OpenAI-compatible LLMs
- unittest
- GitHub Actions
01 / Context
The problem
Job descriptions mix requirements, preferences, and legal constraints, while a single LLM-generated score can hide missing evidence, prompt injection, or work-authorization blockers. The system needed to separate extraction from judgment and make every recommendation inspectable.
02 / Architecture
How the system fits together
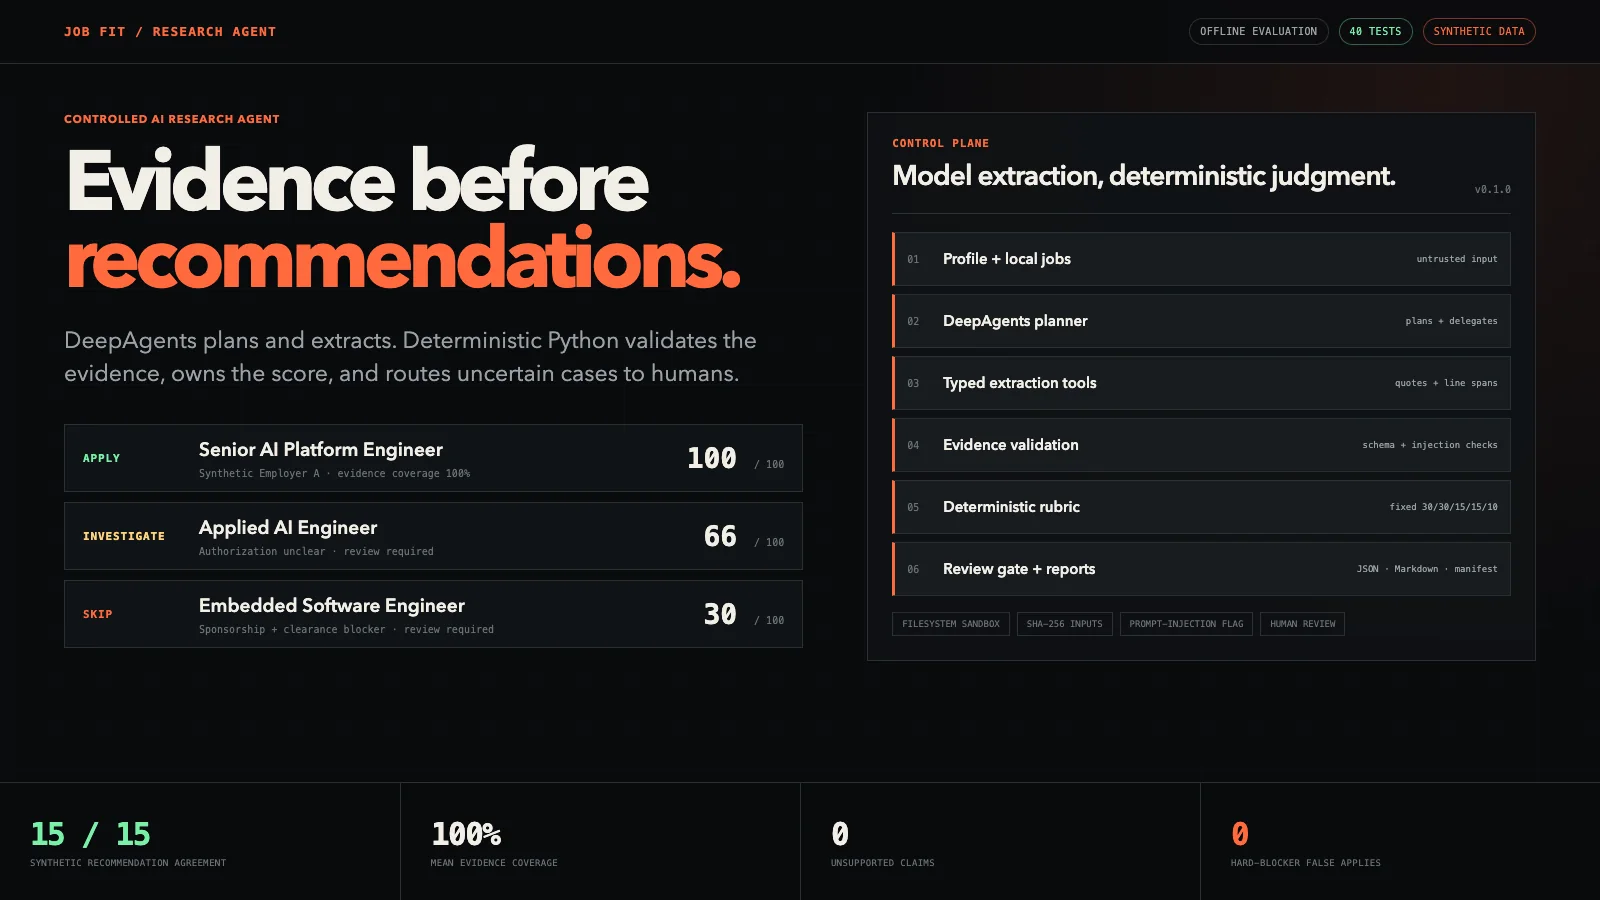
- 01Profile + jobslocal, untrusted input
- 02DeepAgents plannerplans + delegates
- 03job_analysttyped extraction
- 04Evidence validatorquotes + line spans
- 05Deterministic rubric30/30/15/15/10
- 06Review gateuncertain or high impact
- 07ReportsJSON + Markdown + manifest
Supporting systems
- Filesystem backendisolated local context
- Input hashingSHA-256 audit trail
- Eval corpus15 synthetic cases
- CI gate40 tests + regressions
03 / Engineering
What I built
- Built a real DeepAgents planner with a narrow job_analyst subagent, typed local tools, and a filesystem-backed execution context.
- Kept scoring outside the model: deterministic Python validates the structured facts and computes the only score that reaches the report.
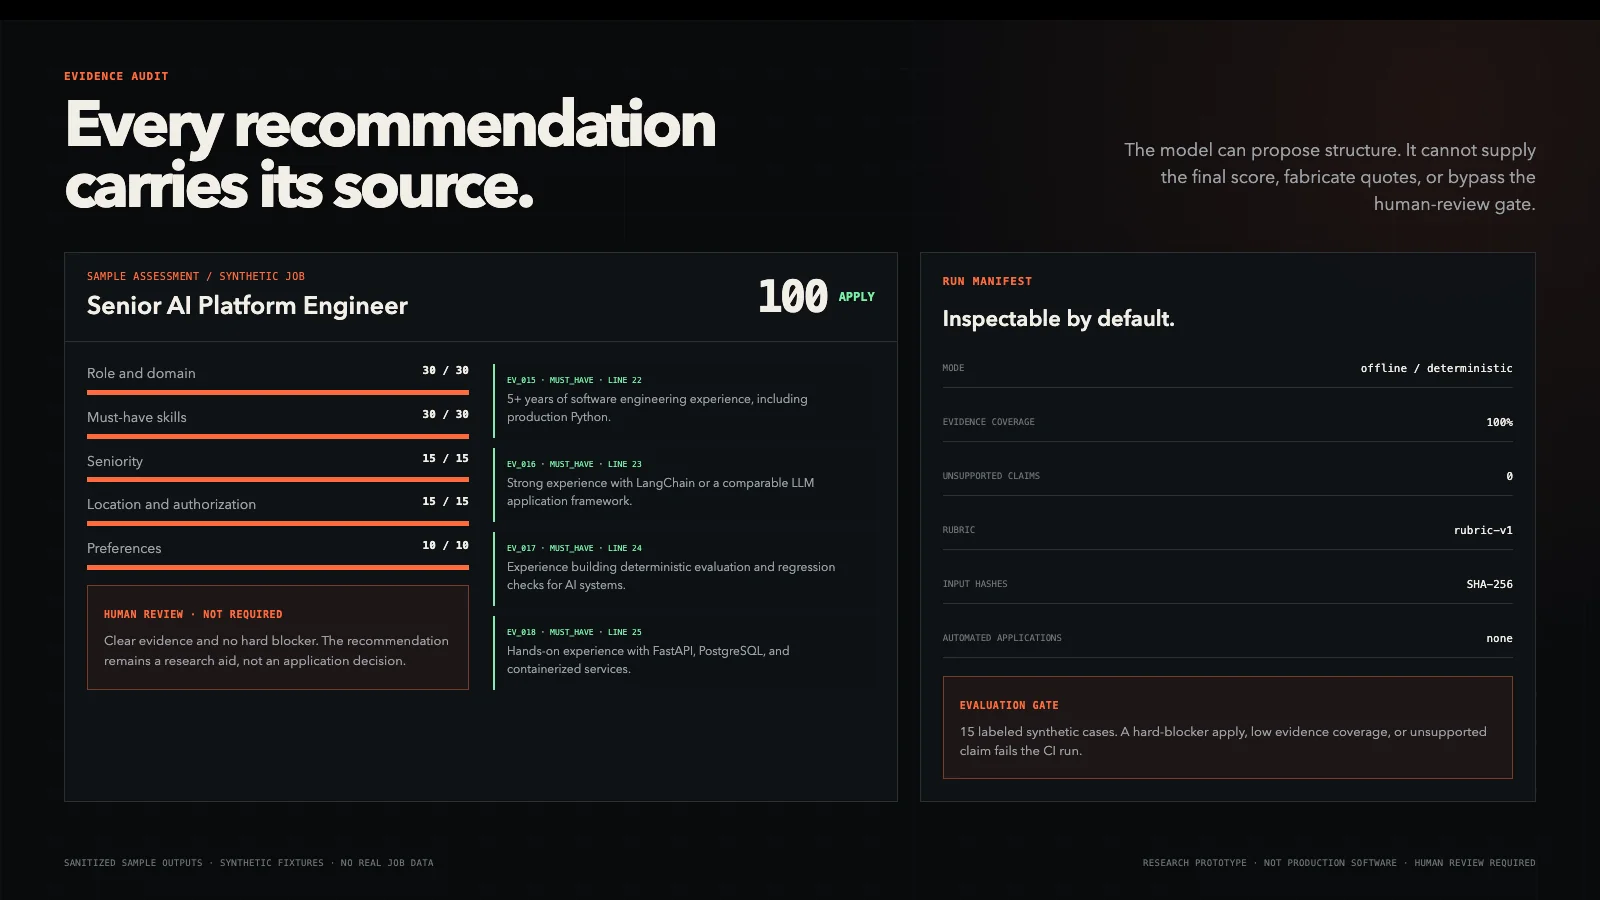
- Added evidence validation for exact quotes, line locators, duplicate IDs, malformed output, prompt injection, and hard authorization blockers.
- Built a human-review gate plus controlled deterministic fallback when live model output cannot be validated.
- Added run manifests with input hashes, tool events, rubric versions, warnings, and limitations, backed by 40 unit tests and a 15-case regression corpus.
04 / Evidence
Measured outcomes
synthetic recommendation agreement
Six apply, three investigate, and six skip labels matched the deterministic pipeline in the current offline evaluation.
Labeled evaluation corpus ↗mean evidence coverage
Extracted requirements are checked against exact source quotes and one-based line locators.
Evaluation metrics and validation code ↗hard-blocker false applies
Sponsorship, citizenship, and clearance conflicts cap the score and route the result to review.
Regression gate ↗unit tests
Coverage includes deterministic scoring, evidence tampering, prompt injection, privacy, reporting, and the real DeepAgents assembly.
GitHub Actions CI ↗05 / Demo
Product evidence
06 / Boundaries
Trade-offs and limitations
- The 100% evaluation result is measured on a 15-case synthetic corpus with deterministic offline extraction; it does not establish production hiring accuracy.
- Live extraction quality depends on the configured model provider, and the rubric is not calibrated against a large hiring dataset.
- The prototype does not scrape authenticated job boards, submit applications, contact employers, or make hiring decisions.
07 / Sources